Inco AI Launches Its Inference Platform, Leading Across Four Open Models on Artificial Analysis

Kimi K3 · 1 / 4
Over the last several months, Inco AI has been building an inference stack purpose-built for the demands of the agentic era and pushing the efficiency frontier across sustained generation, long-running workloads, and longer sequences—conditions that combine to push inference systems to their limits.
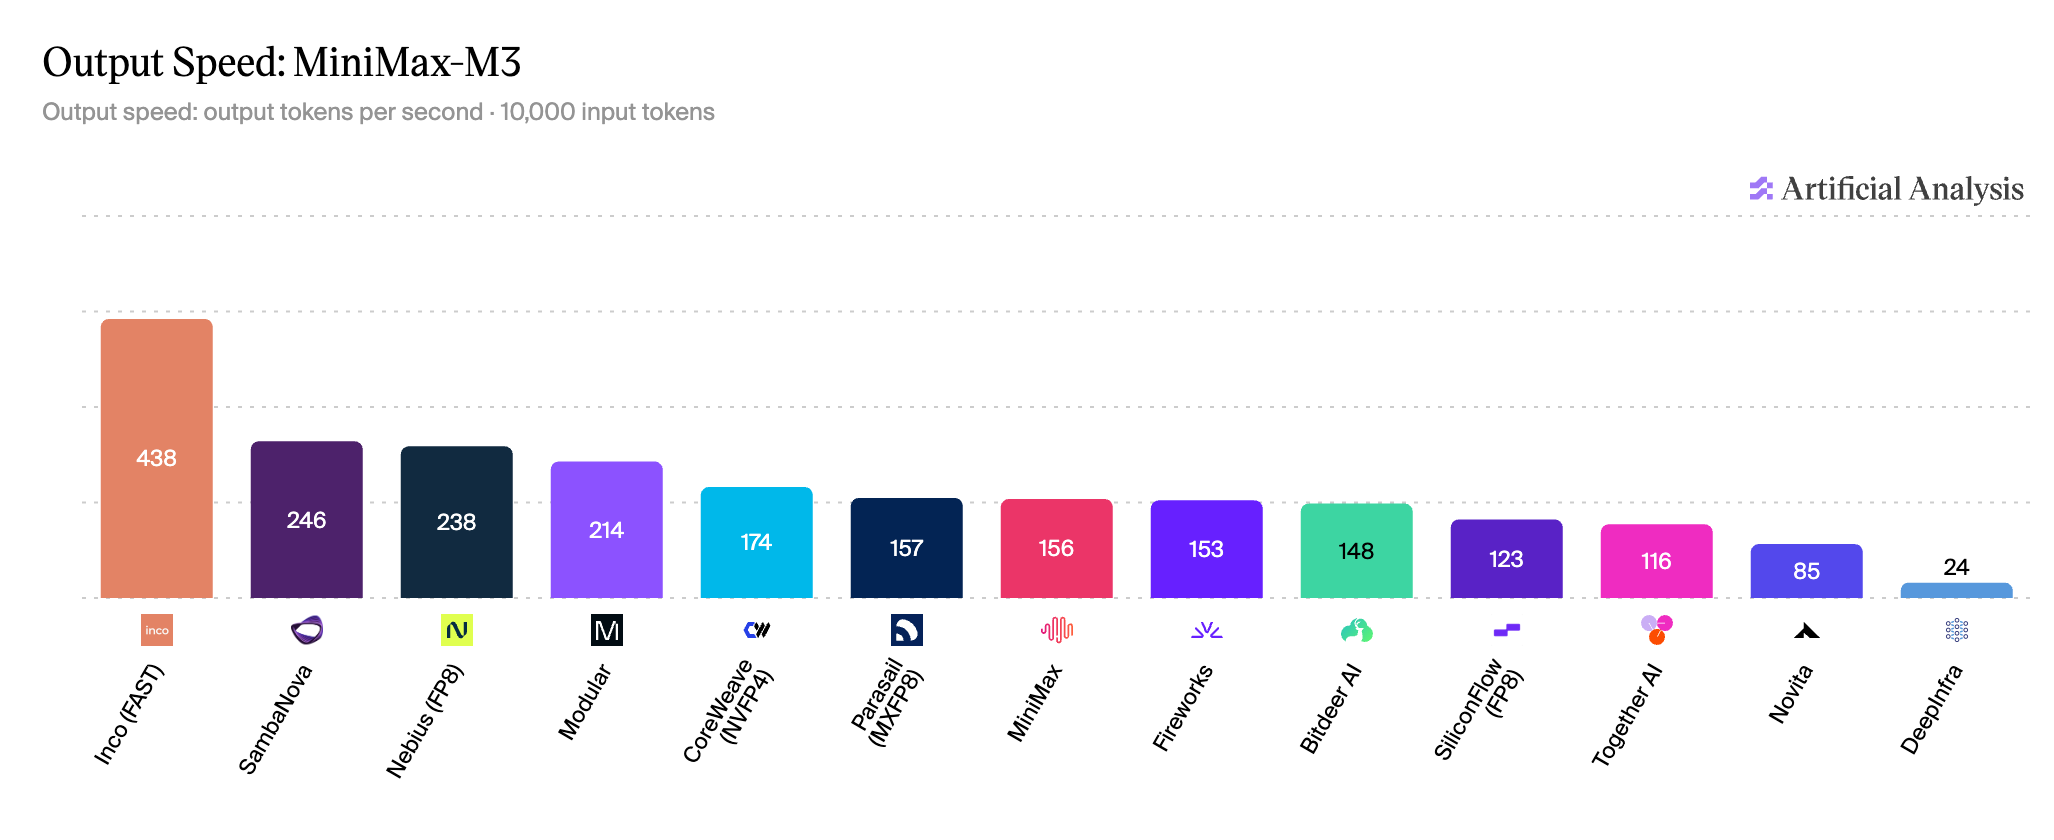
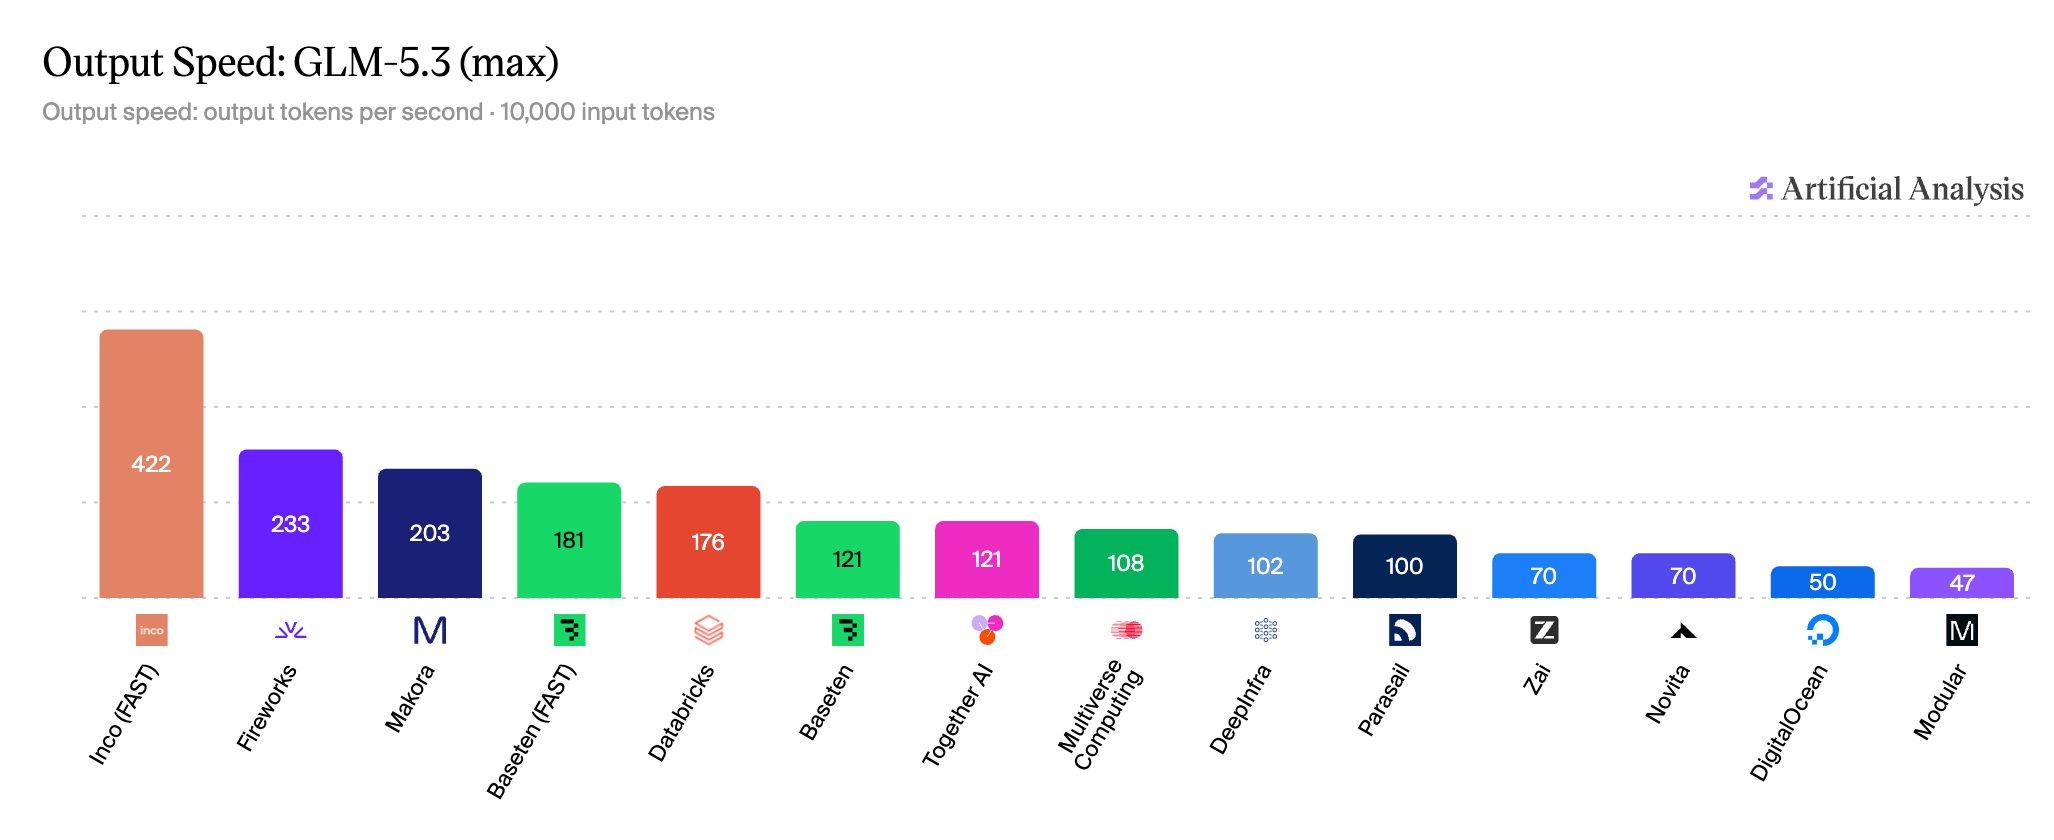
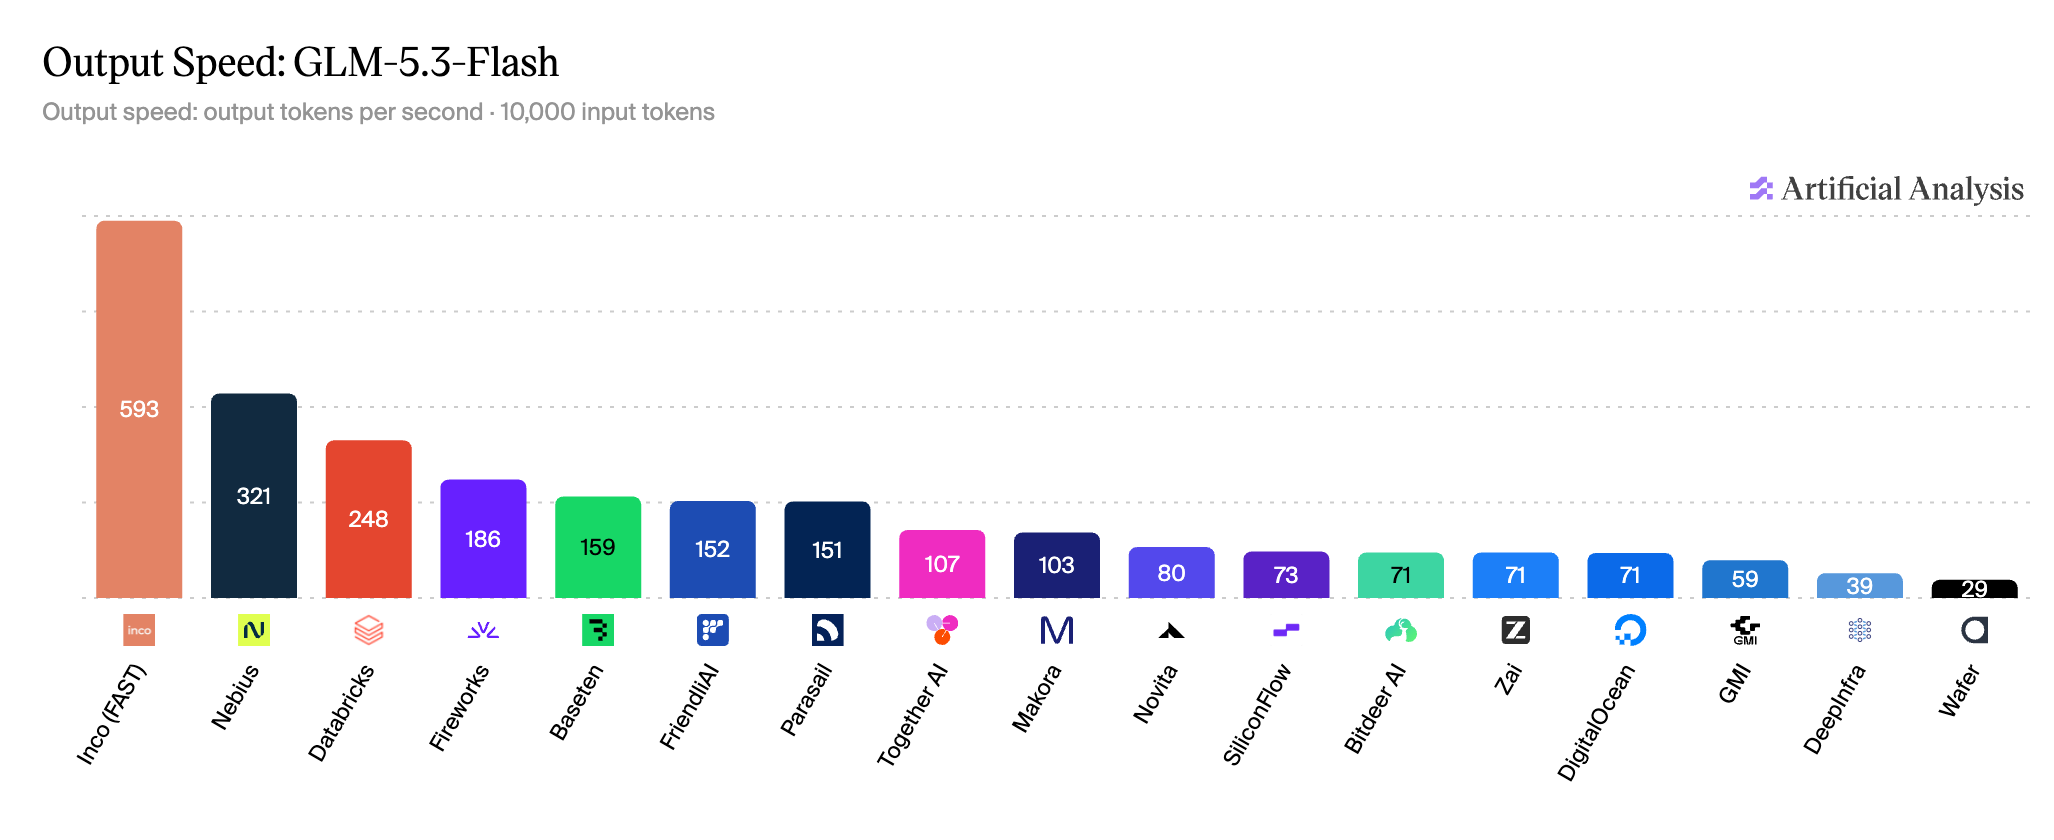
Today's launch of the Inco platform marks an important milestone toward bringing superior agentic inference performance to market and provides a first look at Inco's inference and technology stack. We are releasing high-speed endpoints for Kimi K3, MiniMax M3, GLM 5.3, and GLM 5.3 Flash. Each leads its respective Artificial Analysis provider leaderboard on output speed.
| Model | Output tokens / s | Peak TPS | Relative improvement |
|---|---|---|---|
| Kimi K3 | 326 | 434 | 1.78× |
| MiniMax M3 | 438 | 671 | 1.78× |
| GLM 5.3 | 422 | 585 | 1.81× |
| GLM 5.3 Flash | 593 | 704 | 1.85× |
Inside the Inco Inference Stack
The Artificial Analysis results reflect optimization across the full Inco stack, highlighting our unique approach to bringing peak inference efficiency to the market.
- 01Fleet-scale servingOrchestration, scheduling, cache-aware routing, and cache management across a growing GPU fleet already serving live production traffic. More to share soon.
- 02Speculative decodingThe Inco inference stack is powered by DFlash and DFlash 2, parallel block-diffusion speculative decoding techniques invented by the Inco team. Open-source checkpoints are already available.
- 03Model quantizationWe are the team behind industry-leading quantization research, including AWQ and ParoQuant. Inco endpoints run on our quantized checkpoints, including day-0 NVFP4 support for GLM 5.3.
- 04Kernel and runtime optimization agentsPurpose-built agents adapt low-level execution to each model and hardware target inside Inco Engine. More to share soon.
The Inco Platform Is Entering Public Beta
We are opening beta access to the Inco platform, starting with Kimi K3, MiniMax M3, GLM 5.3, and GLM 5.3 Flash.
Sign up to try our fastest endpoints on the Inco platform.
Available at launch
- Kimi K3
- MiniMax M3
- GLM 5.3
- GLM 5.3 Flash
If inference speed is on your application's critical path, reach out at contact@inco.ai.
Decode newsletter
Decode with us.
Stay in the loop about research, releases, and ideas about the frontier of efficient inference
One email when we publish something new. Unsubscribe anytime.